
Posts
Agent evals: measuring the noise before comparing agents
In our previous post we replaced a team of agents with one agent loop. It diagnosed 1.5x as many faults without the Kubernetes tools, at 60% less cost. But there is a problem with evaluating agents. Running the same system twice can give very different results, and in our runs the same build, run twice, moved between 0.65x and 1.38x. So how much of the gain was real and how much was noise? That is what we set out to measure.
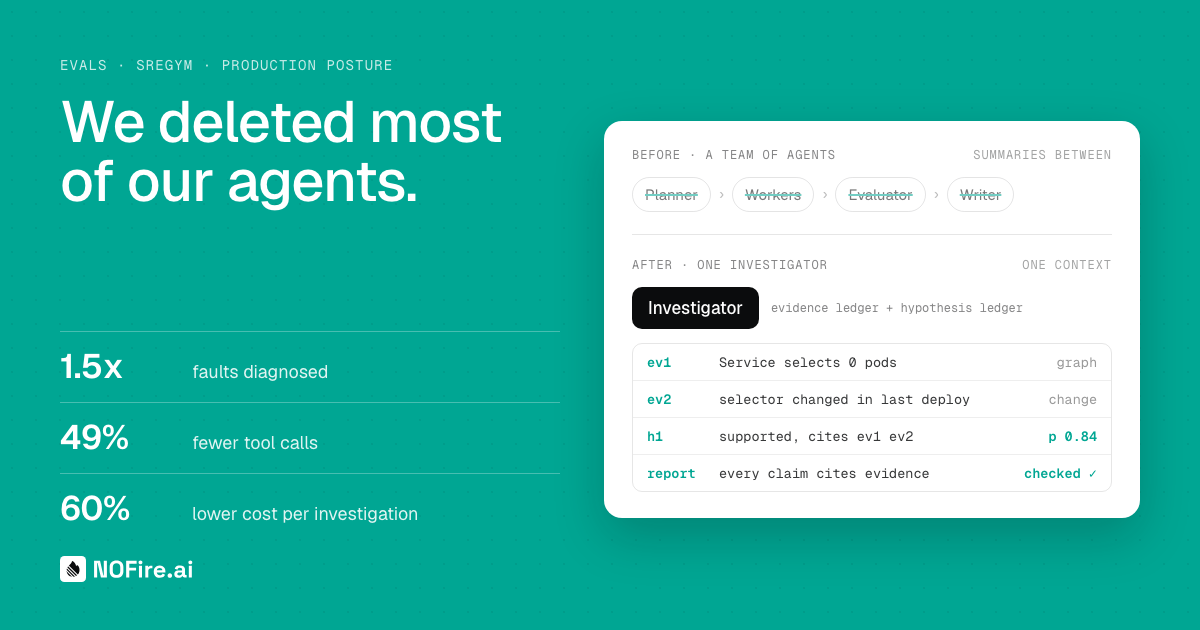
We deleted most of our agents. Our evals told us to.
Earlier this year, we ran NOFire’s root cause investigations on a multi-agent architecture. Daily evals against SREGym and our own test cases showed us what actually improved diagnostic accuracy. A single agent loop delivered the best results: it diagnosed 50% more faults with 49% fewer tool calls, cut the cost per investigation by 60%, and reached a diagnosis 2.5× faster.